Is Agenta worth adopting? A prompt that passes one more test may still be unfit to ship
Teams that often revise prompts and hand them off for review can use Agenta to compare versions, individual results, and execution traces. Define critical cases using synthetic tests, then weigh the value of review against evaluation and upkeep costs.
A team revises a support prompt to answer common questions more clearly, but one case with no processing record now produces “Your refund is complete.” If such changes are frequent and another colleague has to review them, Agenta’s value lies in putting versions, test results and execution traces together. If prompts rarely change and your repository and offline tests already let you trace issues, there is little reason to add a platform.
Tie the difference between versions to individual cases
Agenta’s Prompt & Configuration Registry supports side-by-side comparisons and records deployment environment history. Its evaluation dashboard shows individual inputs, outputs, scores and the traces that generated them. Before the trial, confirm that your intended version or deployment provides the evaluation dashboard, version registry and trace fields you need. If you cannot confirm access, do not adopt it. In a test environment with no real business permissions, compare the old prompt A and new prompt B on fixed synthetic cases. Keep the model, parameters and evaluation rules fixed; change only the prompt. Record both version identifiers and the test set version so a colleague can find the same input and recorded answer rather than hunting for a score screenshot in chat. That does not guarantee identical wording on a new run.
Try eight support-draft cases. Suppose the old version passes six and the new one seven on the same fixed test set. This is hypothetical, not an Agenta test result. The new prompt fixes two routine replies but claims a refund is complete in the case where there is no refund confirmation. Have a human mark that as a critical failure. Return the new version for revision even though the total rose. Set that rule before seeing results. Format can be checked automatically; unconfirmed business commitments need human review. Evaluate drafts only, without connecting refund or outbound messaging tools, and do not treat a passing evaluation as permission to ship.
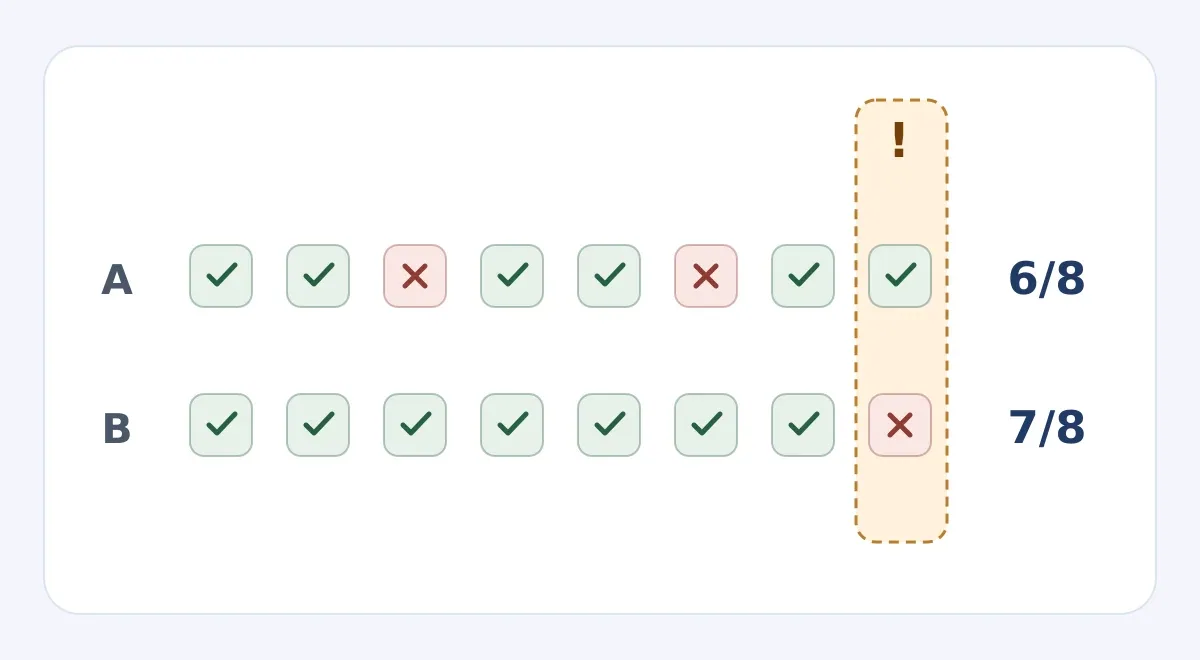
Illustrative example, not a product screenshot or test result. The dashed column marks the case the team defined as critical: without refund confirmation, the draft must not claim the refund is complete. A reviewer still sends B back despite its higher total.
Use one review handoff to decide whether to add the platform
Ask someone who did not make the change to find the failed case, check both answers and use the version diff and trace to locate the problem. If the trace lacks the intermediate details you need, having a trace does not mean you can explain the error. Check what test data and trace fields may be stored; use synthetic input only, not original customer messages or production keys. Verify that you can find the previous configuration and rehearse restoring it in the test environment. Rolling back a prompt does not undo any external action already taken.
Record time saved on diagnosis and handoff, less test-set upkeep and any additional human review. For the model budget, suppose you run the same eight cases for each of two versions, three times. That makes 48 draft generations. If another model scores each draft, count 48 more scoring calls. Three rounds are a budgeting assumption, not a reliability guarantee, and humans still review critical cases. Generation and scoring may cost money in the old workflow too. List those common costs separately from the new platform, integration or self-hosting overhead.
Agenta’s open-source announcement lists evaluation, prompt management and observability as open-source core features, while some advanced collaboration features such as role-based access, single sign-on and audit logs are separately licensed. Self-hosting does not remove the need to check which governance features you require. Expand only if critical cases hold up, others can retrieve the saved inputs and results, and the value of time saved covers incremental costs. If your main problem is missing test coverage for real risks, improve the test set before switching tools.
Content note:This article is based on publicly available information and is intended as a reference for evaluating tools. Features, pricing, and related policies may change at any time; please refer to the latest official information.
Original source:www.agenta.ai