Is AgentConnect worth self-hosting? Test the handoff when its second runner stops
For teams managing different runtimes and workspaces, AgentConnect can offer one view of handoffs. Compare failure recovery and ongoing operating time with a manual handoff in a synthetic two-runner pilot.
A team with one repository and one terminal agent needn't rush to self-host AgentConnect. It earns a place on the shortlist when two groups need a common handoff record but want to keep their own runtimes and workspaces. Instead of counting chat integrations, check the handoff most likely to fail: when the review runner isn't available, will the next person know what actually got done?
Central management, separate execution
The project's repository describes a console for roles, runtimes, workspaces, daemon placement and session visibility, while the daemons run the actual agents. Support for ACP-compatible runtimes makes it possible to administer different environments together. The local Compose evaluation stack does not start agent daemons by itself; someone still owns deployment, upgrades and monitoring. The repository's hosted path is listed as a waitlist, so don't make a hosted purchase a prerequisite for a self-hosted evaluation.
Use a synthetic change to an internal document. One runner reads two versions and lists changes; the second reads a checklist and reviews them separately. Use approved temporary environments, invented data and read-only workspaces. People initiate and hand off the work; leave chat integrations, live triggers and publishing off. App visibility is not OS isolation, and the runtime does not promise offline operation. Confirm the model and data path before testing, and never load real material.
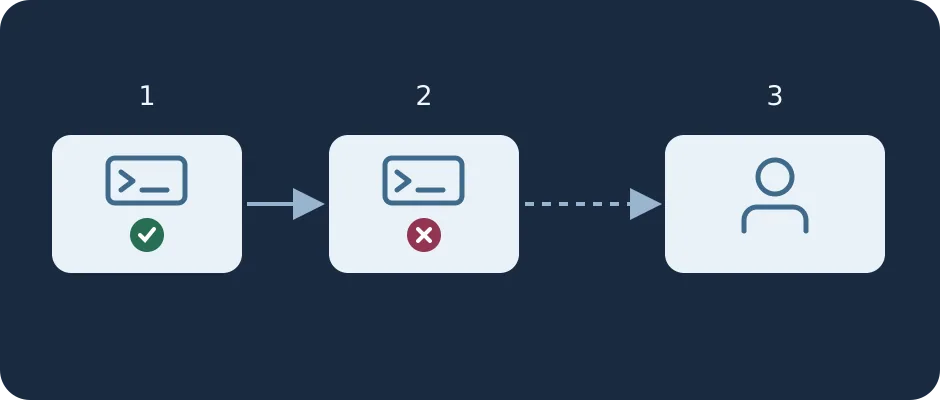
Stop the evaluation runner and compare both routes
Run the same task with two terminal sessions and a manual handoff sheet, then with AgentConnect's shared view. Ask a colleague to check who handled it, which version they used and whether a review exists. Stop the second evaluation runner before review. A usable handoff shows the review is still open and returns it to a person; the first runner's summary is not a sign-off. Track handoff minutes, repeated evidence searches and time spent operating the runners and model environments. Repeat on another document set.
Expand only if both rounds make the evidence quicker to find, nobody mistakes an unreviewed result for an approved one, and someone can own ongoing maintenance. For low volume or a manual log that already separates analysis from review, the terminals and log are simpler.
Content note:This article is based on publicly available information and is intended as a reference for evaluating tools. Features, pricing, and related policies may change at any time; please refer to the latest official information.
Original source:github.com