Amazon SageMaker AI with managed MLflow: check the validation snapshot before comparing scores
A fictional parcel classifier tests whether a second maintainer can distinguish a comparable run from one on different data.
Goze lists Amazon SageMaker, the broader platform. This guide is about its model-development component, SageMaker AI. AWS launched managed MLflow in 2024; it can track parameters, metrics, tags and artifact locations by run. A well-logged score still isn't a fair comparison if the validation data changed.
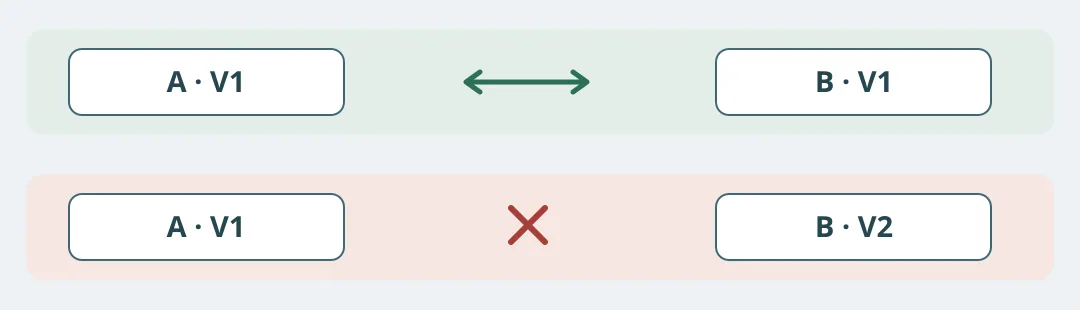
Figure 1. Original acceptance diagram, not a console screenshot. Put both runs on the same measuring scale first.
Make a parcel-size classifier the handover exercise
Use fictional parcel dimensions and small-box/large-box labels for a local tabletop exercise. Give A and B the same frozen V1 validation snapshot, split, metric and units. Verify that the comparison can be reconstructed from the records. Change B to V2: even a higher score must be marked not directly comparable. Record each run’s snapshot ID or hash, split, script version, metric definition and artifact location. These are fields for your team to record, not a promise that AWS freezes every input automatically.
Ask a teammate to recover the script and snapshot and identify the comparable pair from records alone. Run the same handover with local MLflow or a versioned experiment sheet. Keep it local if a single person runs a few experiments and handover works. If several people repeatedly lose context, compare managed tracking and maintenance costs. Price tracking, artifact storage and compute separately in any actual evaluation; this exercise creates no cloud resources.
Content note:This article is based on publicly available information and is intended as a reference for evaluating tools. Features, pricing, and related policies may change at any time; please refer to the latest official information.
Original source:docs.aws.amazon.com