Arthur buying guide: is wrong-label monitoring worth adding?
Use six fictional results to distinguish false alarms, misses and real detections without automatic blocking.
For a fixed format or mapping, a rule and human spot checks are usually simpler. Consider Arthur’s custom evaluations if several versions need the same output rubric. Its September 2025 release notes confirm custom evals; July 2026 notes describe experiment summaries with rates and per-case statuses. An aggregate rate does not replace inspecting errors. (Source)
Create answer keys for six outputs from a fictional paper-craft catalog: three wrong labels and three correct. Suppose the evaluator catches two wrong labels (TP 2), flags one correct label (FP 1), misses one wrong label (FN 1) and clears two correct labels (TN 2). It finds 2/3 of real errors and 2/3 of alerts are real errors. Those fractions happen to match, but count different things.
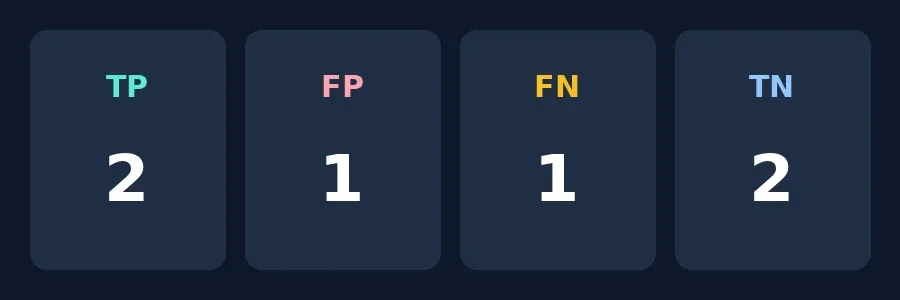
Original result diagram, not an Arthur test. False alarms and missed errors both need review.
Stay in monitor-only mode and compare each result to its label rationale. Use no real traffic and do not infer stable accuracy from six examples. After changing the rubric, replay a separate holdout set. Reject automation if it misses a must-catch case or false alarms erase time savings. Add monitoring only if it catches what human review cannot afford to miss and lets reviewers locate the record. This example does not support automatic blocking.
Content note:This article is based on publicly available information and is intended as a reference for evaluating tools. Features, pricing, and related policies may change at any time; please refer to the latest official information.
Original source:www.arthur.ai