How to use BestLLMfor: check VRAM headroom for two context lengths
Turn public specs into a shortlist, not a hardware guarantee. Two fictional budgets separate model weights, context and runtime overhead.
Use it to screen models, not as a benchmark
BestLLMfor’s August 2026 GPU buying guide starts with VRAM tiers, then checks the model and quantization. Its quantization explanation distinguishes weights from the KV cache that grows with context. This is useful for shortlisting comparable text models, not for certifying compatibility, speed or output quality on your machine. A model’s maximum context and the context your machine can afford are different.
Budget the same model on two sheets
Imagine an 8 GB card. Reserve 1 GB for the system and other programs, leaving a 7 GB budget. Candidate A uses one fixed quantization. Assume weights of 5 GB and 0.5 GB runtime overhead. With 0.8 GB cache for short input, total use is 6.3 GB, leaving 0.7 GB. With 2 GB cache for long input, it takes 7.5 GB and is 0.5 GB over. These numbers are for illustration, not specs for any real model or device.
To compare a similar text model B, use the same input length, output budget and runtime environment, and document each model’s quantization separately. Never compare A’s short input to B’s long input. The first pass should show that A fits the short case but not the long one. Then consider a smaller quantization, shorter documents or a smaller model of the same type. That says nothing about which gives better answers.
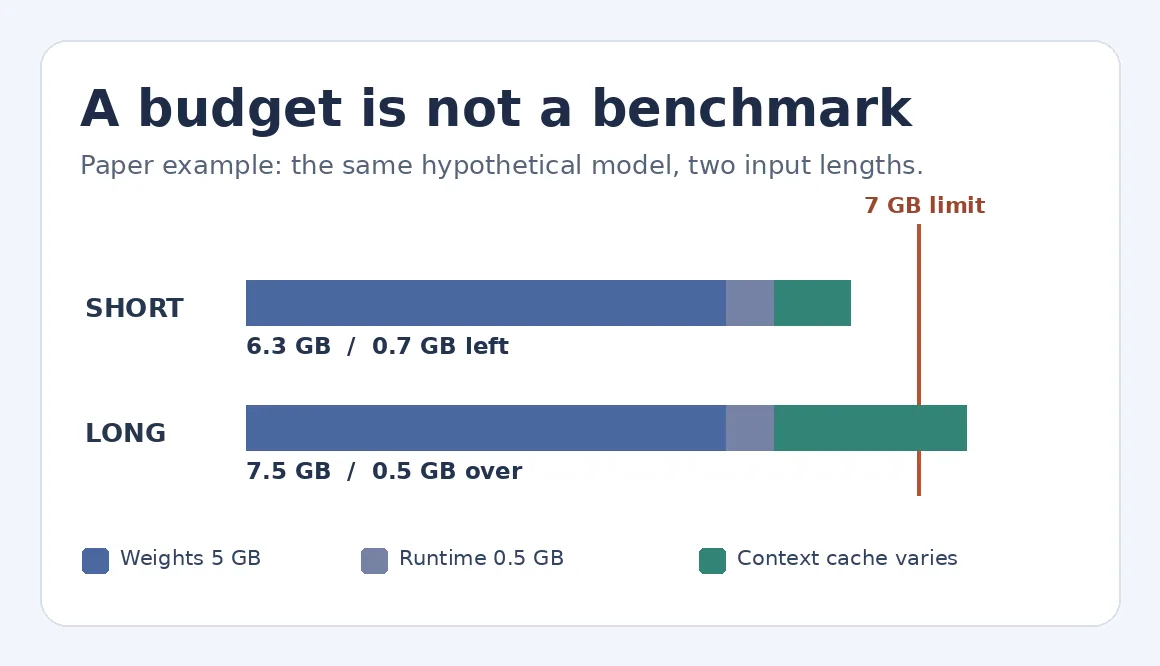
Original paper illustration. Weights and runtime overhead stay fixed while context cache changes. Going over budget does not measure performance.
When not to decide from an estimate
If the model, runtime or quantization is unclear, do not buy hardware based on the estimate. If work mostly involves short text and the existing tool is fast enough, keeping it can be simpler than maintaining a local model. If long documents are required, separate remaining VRAM, accuracy on homemade test sheets and waiting time. Write a fictional catalog, prepare a few questions with known answers and set a maximum wait in advance. The estimate just reduces the list to candidates worth checking. This example downloads no models and runs no software.
Content note:This article is based on publicly available information and is intended as a reference for evaluating tools. Features, pricing, and related policies may change at any time; please refer to the latest official information.
Original source:bestllmfor.com